ESE 2026-Kongress-Selektor – 𝐔𝐬𝐞-𝐜𝐚𝐬𝐞 𝐟ü𝐫 𝐂𝐮𝐬𝐭𝐨𝐦 𝐔𝐗-𝐃𝐞𝐬𝐢𝐠𝐧
Zu Beginn die Klärung, dass ich weder mit dem Embedded Software Kongress verbandelt bin, noch bezahlt wurde etc.
Ich würde gern dieses Jahr nach Sindelfingen reisen, also war es Zeit, die Agenda zu studieren. Die Webseiten bieten einen guten Überblick.
ABER: Sie könnten etwas komfortabler in der Bedienung sein. Denn für eine fundierte Entscheidung brauche ich die Info, was der Vortrag neben der spannenden Headline wirklich aufzeigen möchte. Jeden Vortrag im neuen Tab öffnen und laden lassen? Nee, bitte nicht. Ebenfalls: eine Vorselektion für die für mich relevanten Bereiche: 𝐏𝐫𝐨𝐣𝐞𝐤𝐭- 𝐮𝐧𝐝 𝐓𝐞𝐚𝐦-𝐌𝐚𝐧𝐚𝐠𝐞𝐦𝐞𝐧𝐭, 𝐀𝐠𝐞𝐧𝐭𝐢𝐜 𝐀𝐈, 𝐒𝐤𝐚𝐥𝐢𝐞𝐫𝐮𝐧𝐠.
Also schnell den 𝐄𝐒𝐄_𝐊𝐨𝐧𝐠𝐫𝐞𝐬𝐬_𝐒𝐞𝐥𝐞𝐤𝐭𝐨𝐫 (https://github.com/marcelpetrick/ESE_Kongress_Selektor) in #Python implementiert.
Was brauchen wir hierfür? Einen #Scraper und eine statische Webseite. Der Export der Selektionen erfolgt via JSON. Die Struktur der Seiten wird mehr oder weniger übernommen.
Rasend schnell, Details zum Vortrag werden via Tooltip (statt auf einer neuen Seite) angezeigt, Filterung ist möglich.
Repo klonen und die 𝘱𝘺𝘵𝘩𝘰𝘯3 𝘳𝘶𝘯.𝘱𝘺 ausführen, kurz warten und los geht’s.
𝐖𝐞𝐫 𝐩𝐥𝐚𝐧𝐭 𝐳𝐮𝐦 𝐄𝐒𝐄 𝐳𝐮 𝐟𝐚𝐡𝐫𝐞𝐧? 𝐀𝐧 𝐰𝐞𝐥𝐜𝐡𝐞𝐧 𝐓𝐚𝐠𝐞𝐧?
An die Organisatoren des @ESE: Falls ihr etwas vom Design übernehmen wollt – gern, die GPLv3 macht es möglich.
Video (nicht sichtbar in Vorschau)
Token usage
Friday, I analyzed how many tokens I use. I knew it was a lot. Also more than anyone in my bubble, I was sure of that. But I had never
measured it beyond the built-in “usage” charts you get from some agentic harnesses.
Just to get this clear from the start: I don’t see it as some kind of merit to burn tokens and then brag about it. For me, this is on the same level as buying a luxury car, that bragging part. And i could also tell you how easy it is to misguide a “huge amount of tokens used”-metric. So believe me, all I invested, was for a good purpose.
In the past three years, I got a lot of things done that would not have been possible without generative AI. I grew and explored
lots of new ideas. AI served as 𝐞𝐧𝐚𝐛𝐥𝐞𝐫 and 𝐚𝐜𝐜𝐞𝐥𝐞𝐫𝐚𝐭𝐨𝐫.
So, let’s look at the numbers: somehow, each month, my token usage grows 𝐞𝐱𝐩𝐨𝐧𝐞𝐧𝐭𝐢𝐚𝐥𝐥𝐲. Just by a power of two. But two is
still powerful. Since my usage is split between severval computers and I don’t (yet) use a central portal that collects all the data, I focused on the main machine.
Tokens altogether for the price of ~$3,000 in August 2026. And that month is not over yet. Check the attached chart.
The growth in usage (for me) is easily explained with a historical analogy:
𝕬𝖗𝖔𝖚𝖓𝖉 𝟏𝟓𝟎 𝖞𝖊𝖆𝖗𝖘 𝖆𝖌𝖔, 𝖂𝖎𝖑𝖑𝖎𝖆𝖒 𝕾𝖙𝖆𝖓𝖑𝖊𝖞 𝕵𝖊𝖛𝖔𝖓𝖘 𝖔𝖇𝖘𝖊𝖗𝖛𝖊𝖉 𝖙𝖍𝖆𝖙 𝖒𝖔𝖗𝖊 𝖊𝖋𝖋𝖎𝖈𝖎𝖊𝖓𝖙 𝖘𝖙𝖊𝖆𝖒 𝖊𝖓𝖌𝖎𝖓𝖊𝖘 𝖉𝖎𝖉 𝖓𝖔𝖙 𝖗𝖊𝖉𝖚𝖈𝖊 𝖙𝖍𝖊 𝖔𝖛𝖊𝖗𝖆𝖑𝖑 𝖈𝖔𝖓𝖘𝖚𝖒𝖕𝖙𝖎𝖔𝖓 𝖔𝖋 𝖈𝖔𝖆𝖑.
𝕰𝖆𝖈𝖍 𝖒𝖆𝖈𝖍𝖎𝖓𝖊 𝖓𝖊𝖊𝖉𝖊𝖉 𝖑𝖊𝖘𝖘 𝖈𝖔𝖆𝖑 𝖋𝖔𝖗 𝖙𝖍𝖊 𝖘𝖆𝖒𝖊 𝖆𝖒𝖔𝖚𝖓𝖙 𝖔𝖋 𝖜𝖔𝖗𝖐—𝖇𝖚𝖙 𝖇𝖊𝖈𝖆𝖚𝖘𝖊 𝖙𝖍𝖊 𝖒𝖆𝖈𝖍𝖎𝖓𝖊𝖘 𝖇𝖊𝖈𝖆𝖒𝖊 𝖈𝖍𝖊𝖆𝖕𝖊𝖗 𝖆𝖓𝖉 𝖒𝖔𝖗𝖊 𝖚𝖘𝖊𝖋𝖚𝖑, 𝖕𝖊𝖔𝖕𝖑𝖊 𝖚𝖘𝖊𝖉 𝖒𝖔𝖗𝖊
𝖒𝖆𝖈𝖍𝖎𝖓𝖊𝖘 𝖋𝖔𝖗 𝖒𝖔𝖗𝖊 𝖙𝖍𝖎𝖓𝖌𝖘.
𝕾𝖔 𝖙𝖔𝖙𝖆𝖑 𝖈𝖔𝖆𝖑 𝖈𝖔𝖓𝖘𝖚𝖒𝖕𝖙𝖎𝖔𝖓 𝖎𝖓𝖈𝖗𝖊𝖆𝖘𝖊𝖉.
What are you getting done with the help of agentic support?

Good news: 𝐋𝐕𝐆𝐋 YAML translations with 𝐂𝐮𝐭𝐞𝐋𝐢𝐧𝐠𝐨𝐄𝐱𝐩𝐫𝐞𝐬𝐬 𝟎.𝟑.𝟎
Since #Qt is not the only champion in the embedded domain, I’ve expanded the supported frameworks by making it possible to run it on the #i18n files from #LVGL as well. Maybe it is handy for someone else too 😉
The new mode is invoked with --lvgl-yaml, and you have to do it explicitly. The existing usage for TS files remains unchanged.
The source YAML files also stay untouched, so the result is written to a file named for each output language.
In the background, I also did some other plumbing, which had been on the list for a while: GitHub Actions now also cover the dependency graph, neat badges showing the pipeline states in the README.md, updated dependencies, and some quality hardening. So we have 58 automated tests now, 100% statement coverage, and Pylint reports 10/10.
That polishing and the above-mentioned feature are the result of continuous market review and constant adaptation. New competitors and technical standards emerge; as developers, we should be ready to embrace change and adapt.
Give me feedback if some other translation files need coverage as well.
Link to to the repo: https://github.com/marcelpetrick/CuteLingoExpress


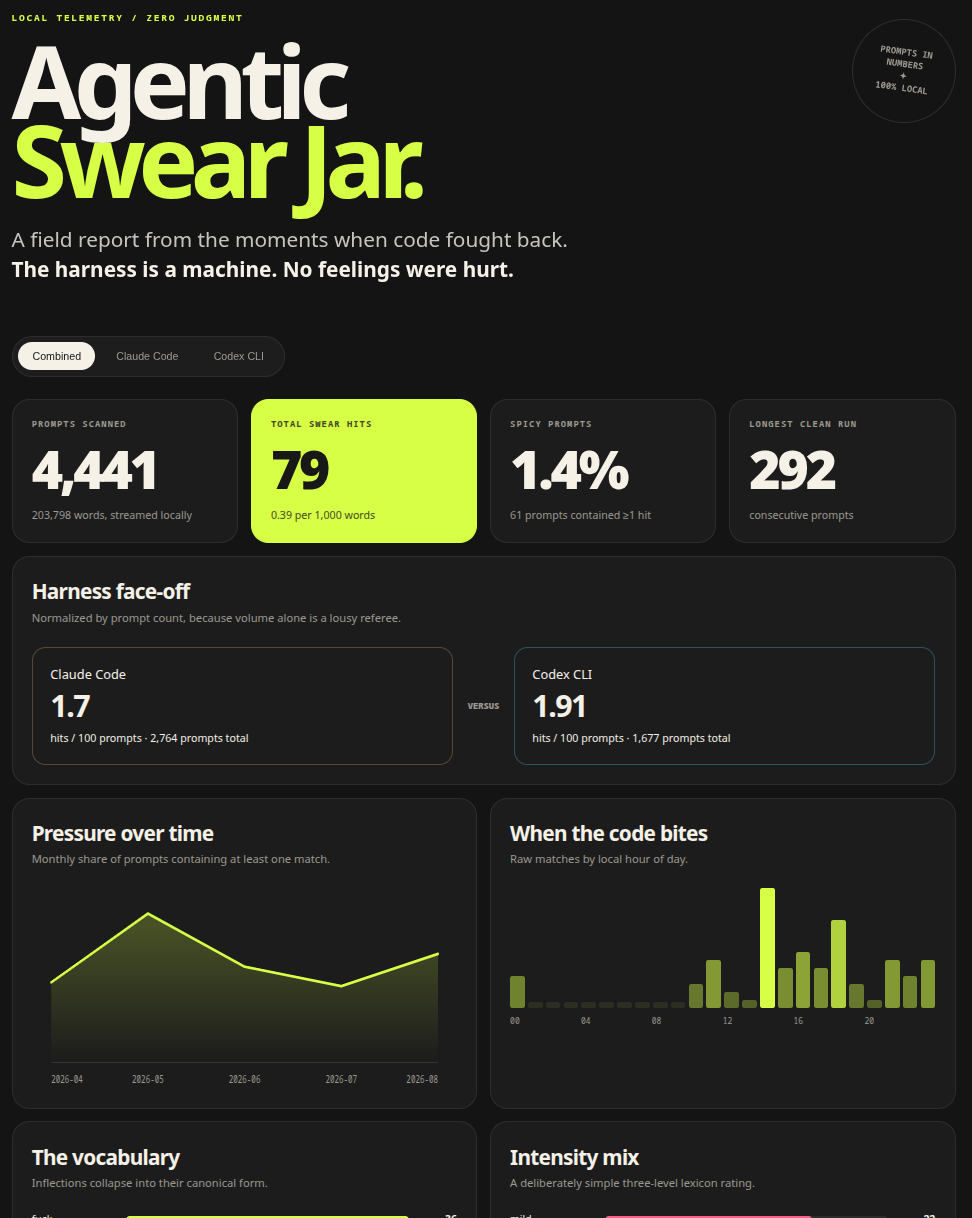
𝐎𝐧𝐥𝐲 𝟐% of my 𝐩𝐫𝐨𝐦𝐩𝐭𝐬 contain 𝐩𝐫𝐨𝐟𝐚𝐧𝐢𝐭𝐲
Testing Muse Glimmer lead to some frustration, so I started the next prompt with something I wouldn’t write professionally.
And this led to the question: how often do I do this? I would have guessed that 10% of my machine-human interactions contain some swear words.
But why guess when you can evaluate the data and produce hard facts?
Therefore I prepared 🫙 𝐀𝐠𝐞𝐧𝐭𝐢𝐜 𝐒𝐰𝐞𝐚𝐫 𝐉𝐚𝐫 as project on GitHub, which evaluates both your 𝐂𝐨𝐝𝐞𝐱 and 𝐂𝐥𝐚𝐮𝐝𝐞 𝐂𝐨𝐝𝐞 logs and gives you on the CLI a short two liner. And additionally you receive an HTML page in nice green IBM 3279-style. All locally, no AI or models involved, just some Python and HTML.
It will reveal to you how many swearwords were used, their frequency, streaks without swearing, which hour of the day the tension rises high, etc ..
What do you think? Anyone has a higher score to offer? Leave me a comment.
GitHub: https://github.com/marcelpetrick/AgenticSwearJar
PDF with full feature view:
Screenshot:
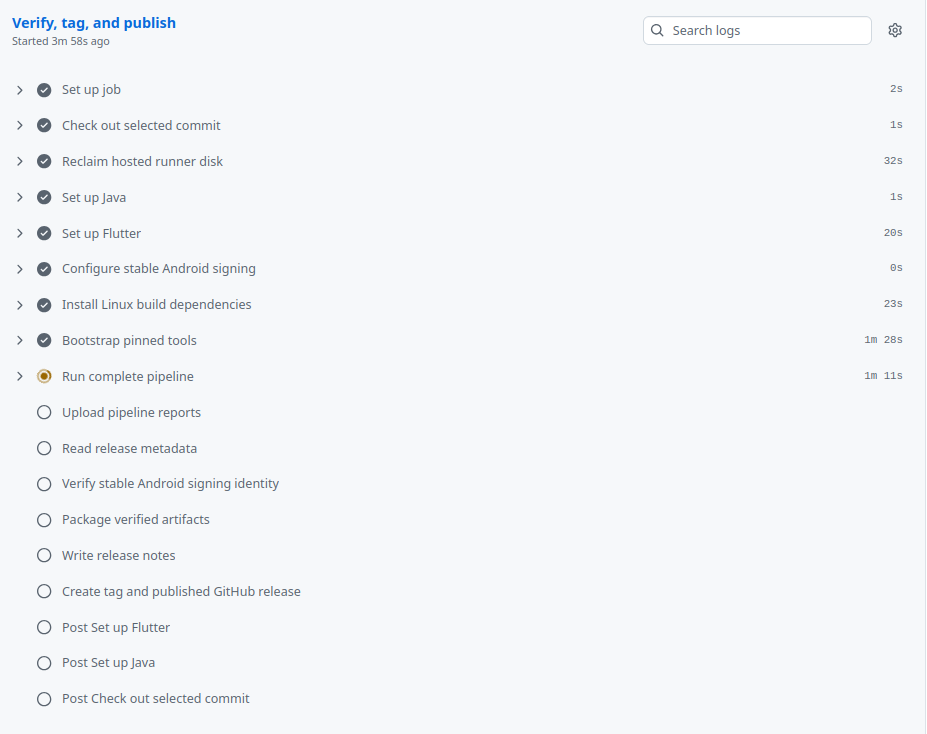
3/x: 𝐂𝐫𝐨𝐋𝐢𝐧𝐠𝐨: pipelines
In a feature-driven world, support-software rarely gets the stage it deserves. Ask a stakeholder what a pipeline is and get 🙃 .. which is sad. Because how else do you want to verify it you built it correctly?
Anyway: automated testing and linting is always part of my process. From day one – not in the final stages. Of course, you should have at least a tiny build-able fragment of your project, but the earlier you add #automation, the better. I usually run with local and continuous integration pipelines.
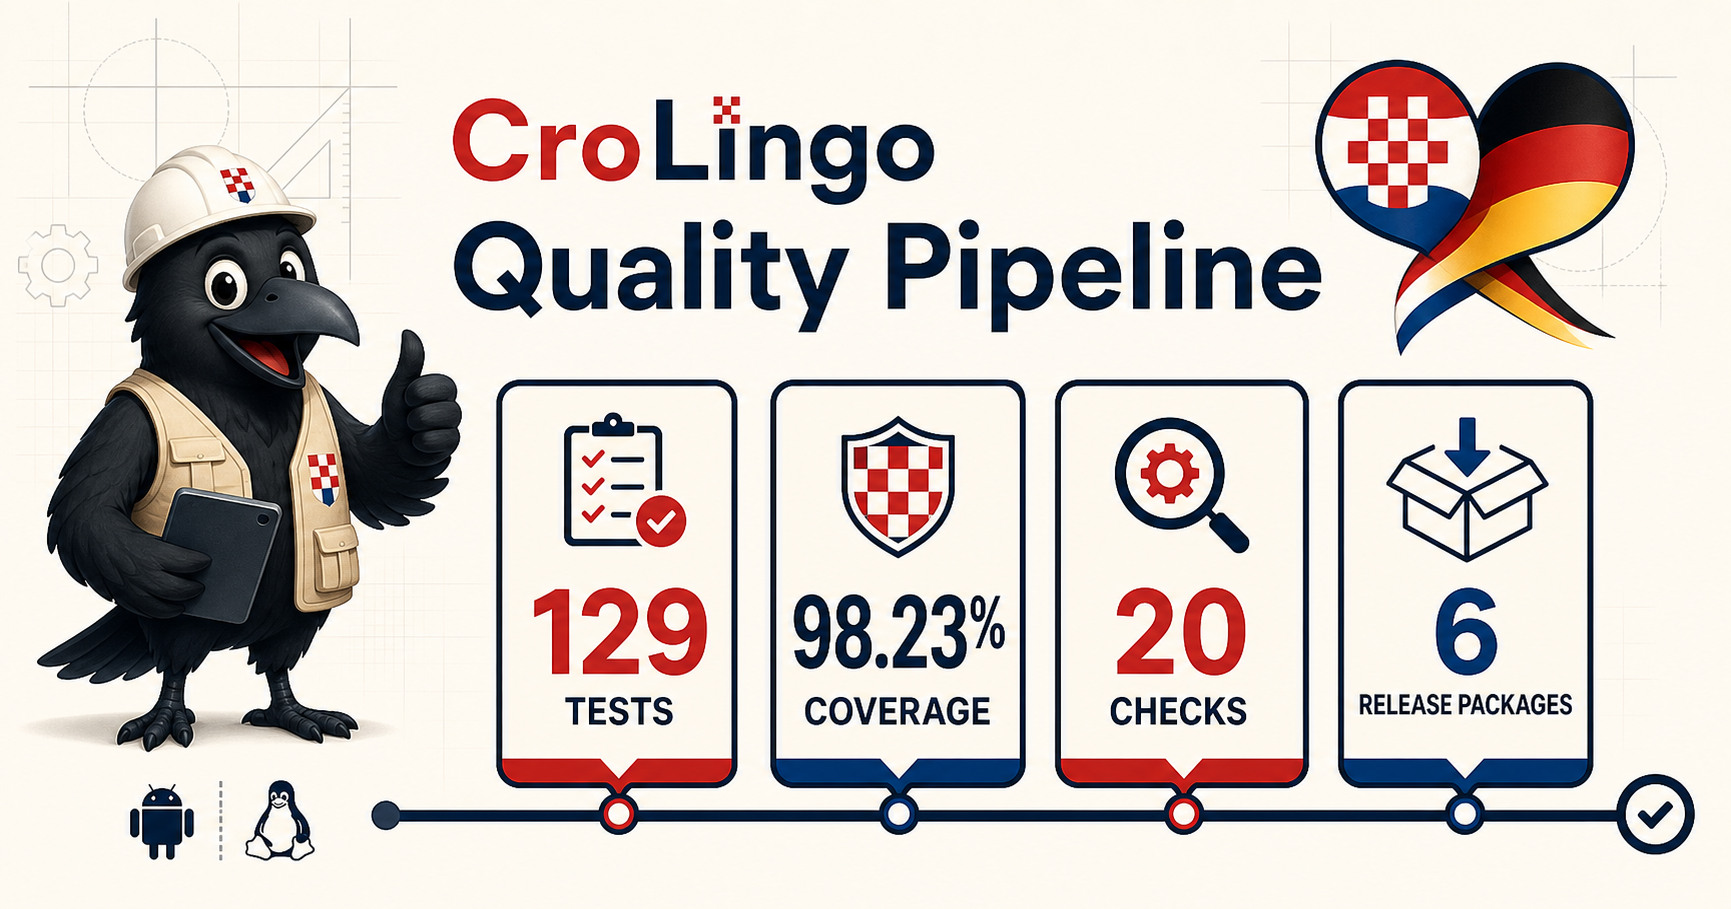
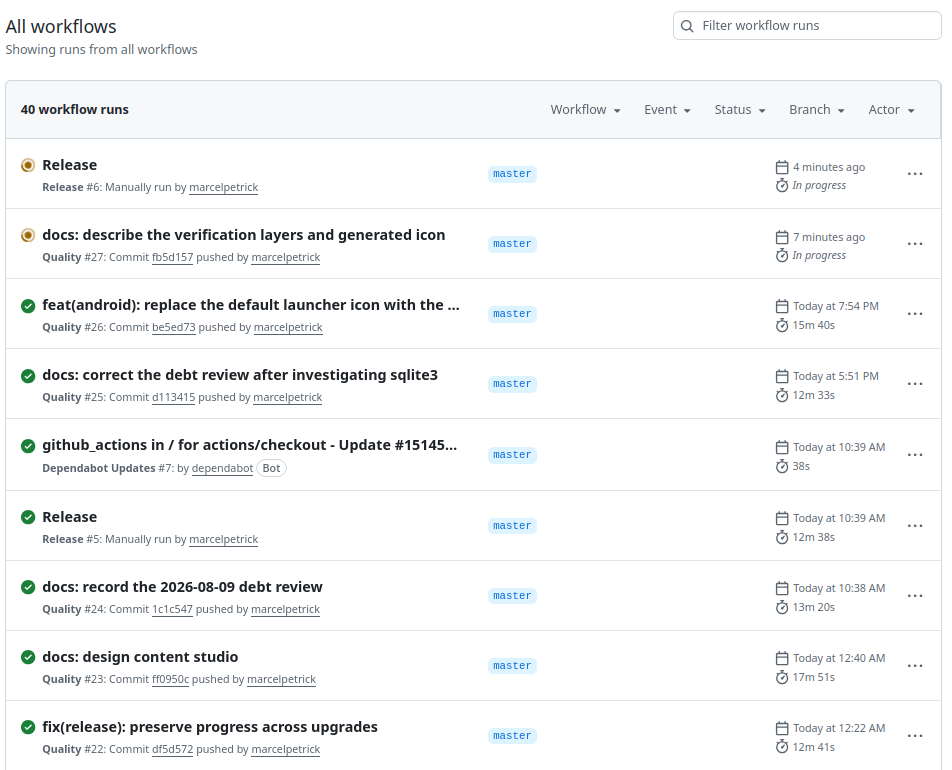
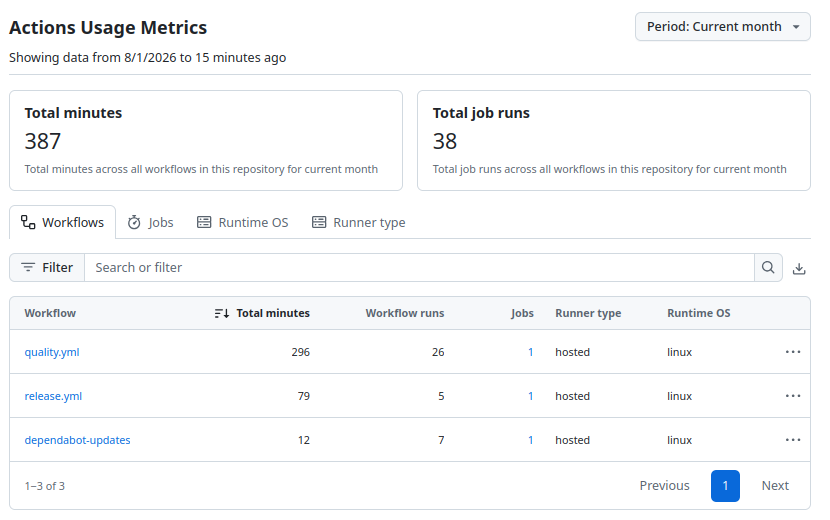
This project is hosted on GitHub, so I went with GitHub actions for the CI. We have 20 named pipeline stages which form a single commit gate. “Cheap” ones like linting and format checks run before the more “expensive” ones, which need a build. 129 automated tests are done, which cover 98% of the code. Together with the 30 unit and widget tests and a real-target integration suite we have fitting coverage. The local version runs as pre-commit hook, the GitHub one is also capable of doing the releases. And so far I made six public releases.
Also, Dependabot is integrated, so if I would miss the release of any dependency, then this neat little bot would create an automatic PR (pull-request) for me. 🐦⬛
The pipeline turns engineering expectations into executable policy. 𝐈𝐭 𝐰𝐨𝐧’𝐭 𝐛𝐮𝐢𝐥𝐝 𝐨𝐫 𝐩𝐚𝐬𝐬, 𝐲𝐨𝐮 𝐜𝐚𝐧’𝐭 𝐫𝐞𝐥𝐞𝐚𝐬𝐞. 𝐒𝐢𝐦𝐩𝐥𝐞 𝐚𝐬 𝐭𝐡𝐚𝐭.
If you want to give this Croatian-German-language learning app a try, download the package from https://github.com/marcelpetrick/CroLingo/releases/tag/v0.0.63 and run it on your Android phone.
Have fun and enjoy learning!
I’ll keep you updated on what comes next. 🇭🇷 ❤️ 🇩🇪
#continuousIntegration #continuousDeployment #pipelines #automation
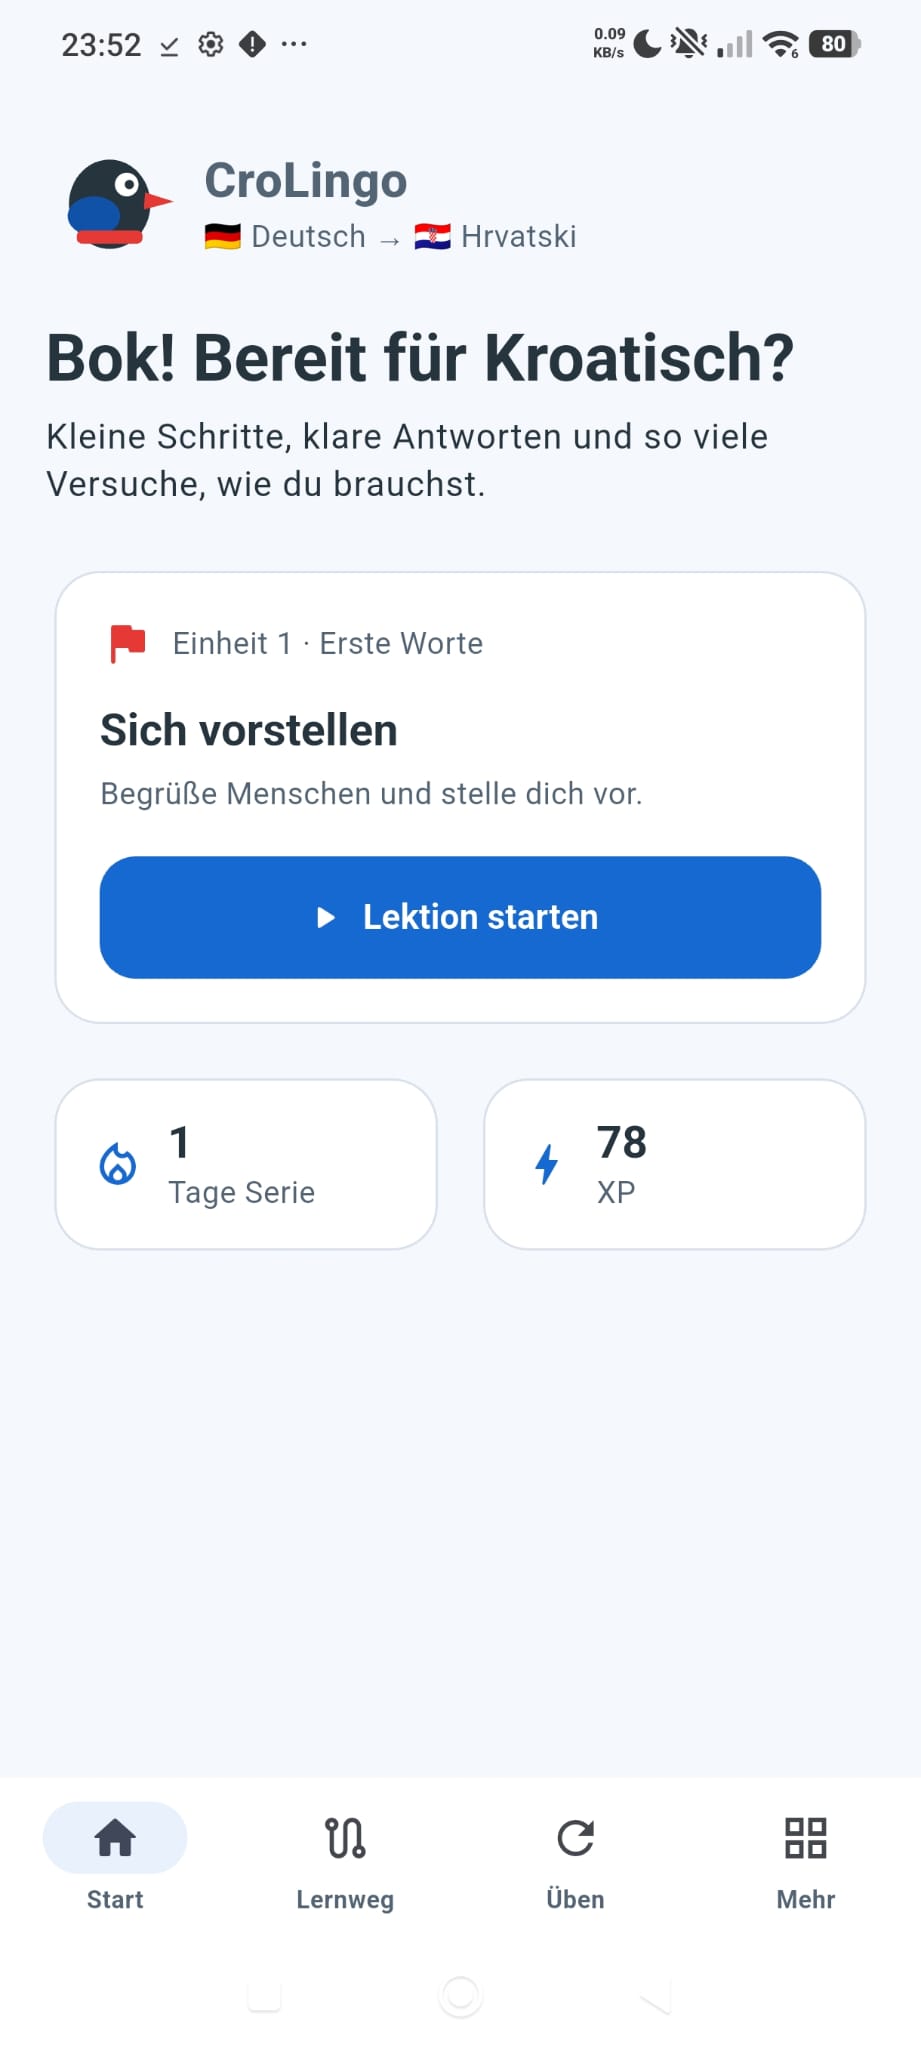
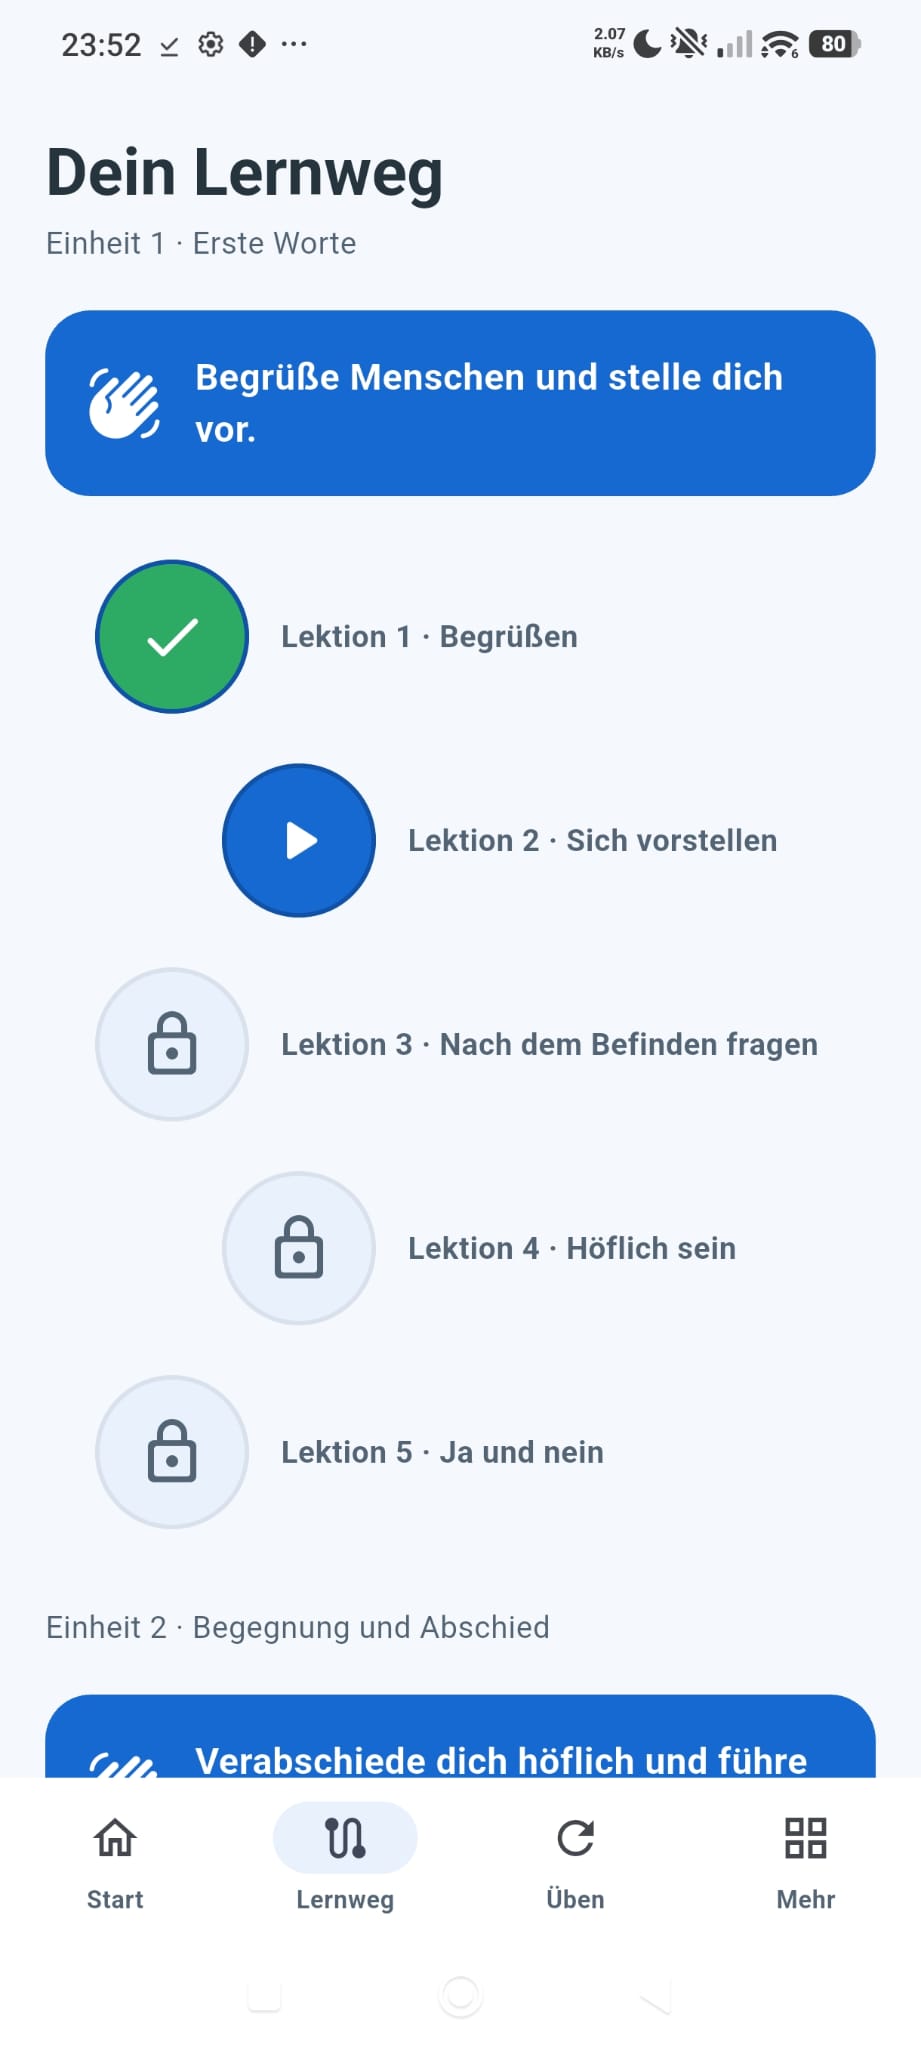
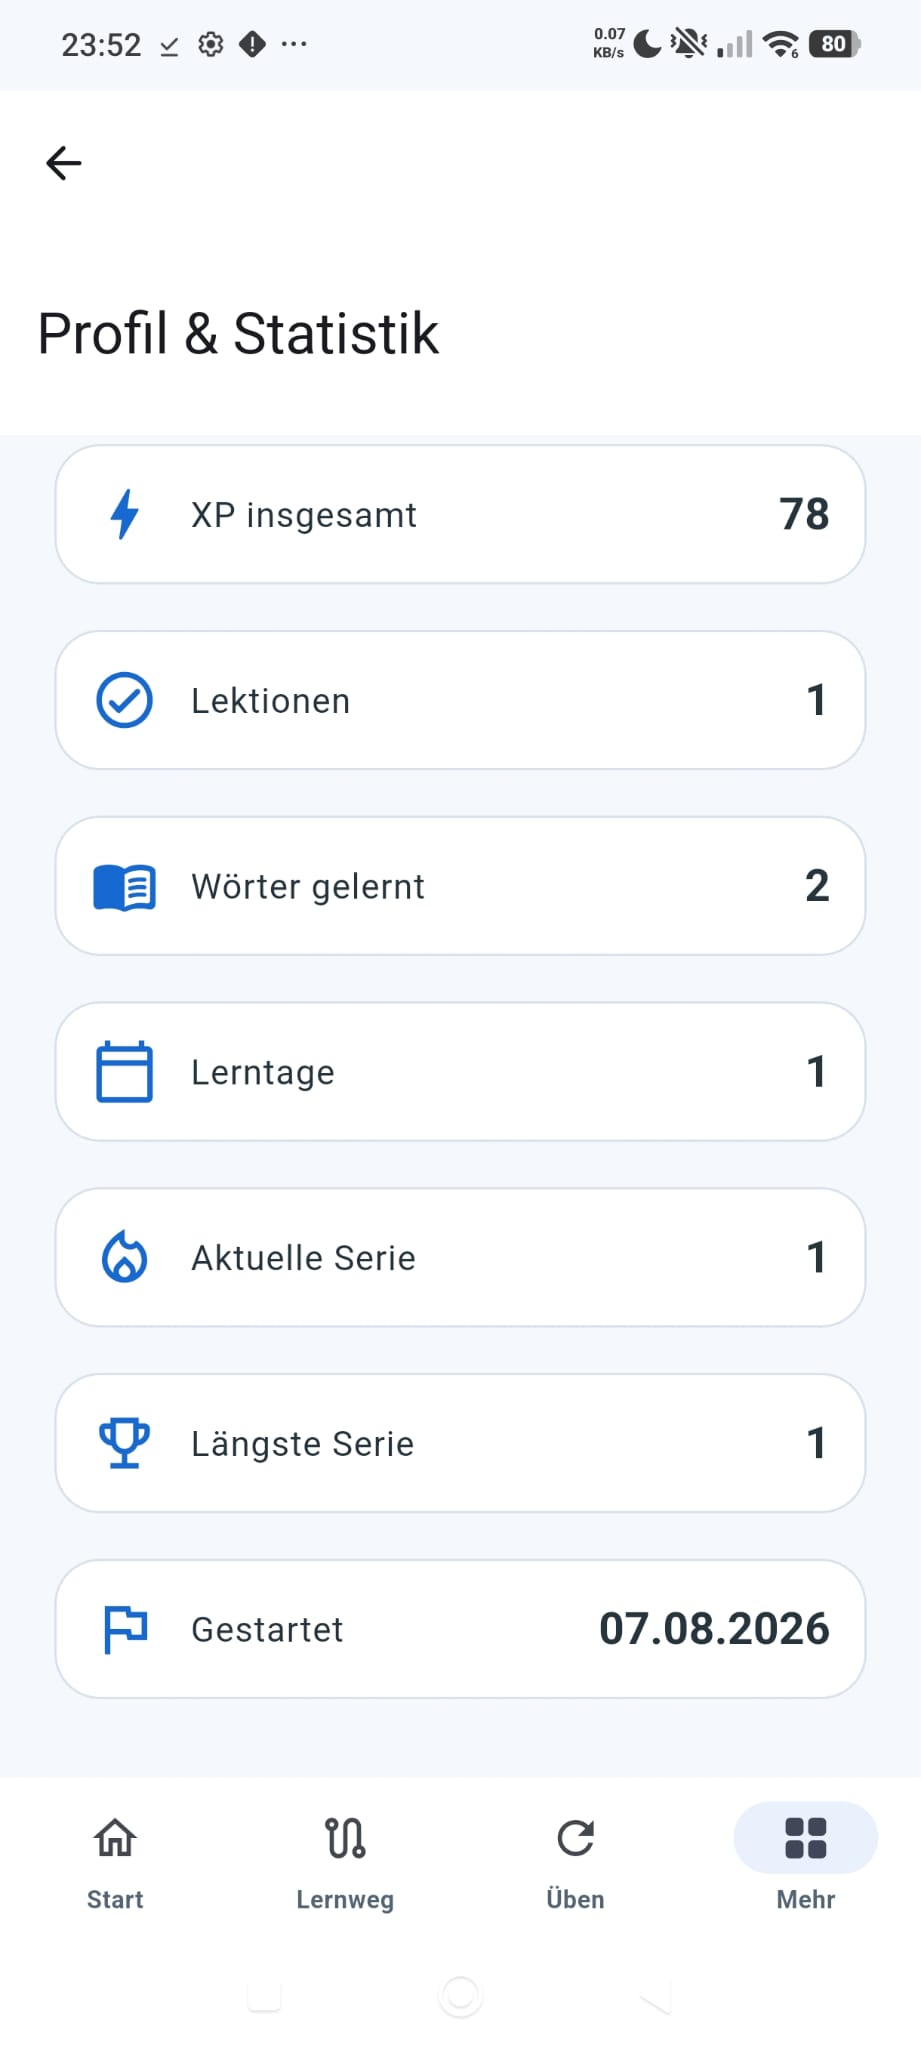
2/x: 𝐂𝐫𝐨𝐋𝐢𝐧𝐠𝐨
As written, I had started to gather all ideas and document what we want. Of course, there exist magic tools which transform unstructured input into well-defined #requirements and which help you to make them conflict-free, unambiguous, atomic, feasible and verifiable. Yada yada, you know the drill.
Then the development started, and we have a first #MVP (minimum viable product) now, as an Android release package and Linux Desktop build. The first content has been added, so the first user feedback could be gathered today. I have to admit, offering an app with well-known competitors yields a lot of “oh, but here it should behave like this” … anyway, input from the target audience is really dear to me. So we now have plenty more things to implement and some to adjust. But we did not experience a single crash or logic deadlock.
✨ 𝐀𝐧𝐝 𝐬𝐨𝐦𝐞 𝐮𝐬𝐞𝐫𝐬 𝐜𝐨𝐮𝐥𝐝 𝐚𝐥𝐫𝐞𝐚𝐝𝐲 𝐥𝐞𝐚𝐫𝐧 𝐬𝐨𝐦𝐞 𝐧𝐞𝐰 𝐰𝐨𝐫𝐝𝐬. ✨
I’ve added on-device screenshots from one of the recent builds. If you want the hands-on experience, go to https://github.com/marcelpetrick/CroLingo/releases/tag/v0.0.40
I’ll keep you updated on what comes next. 🇭🇷 ❤️ 🇩🇪
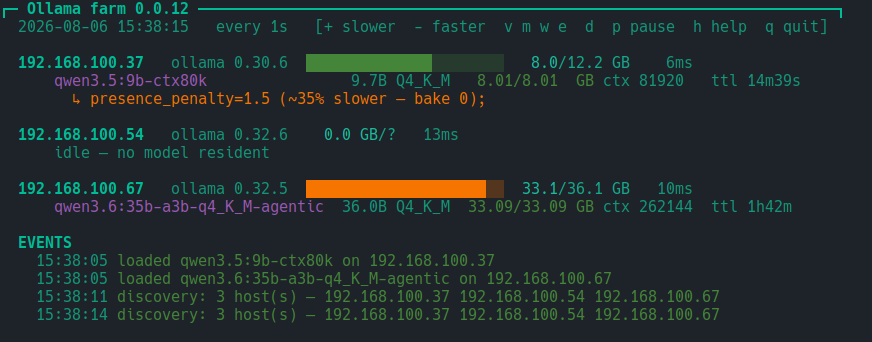
🦙 Release: 𝐎𝐥𝐥𝐚𝐦𝐚𝐅𝐚𝐫𝐦 ✨
Recently I had the need to monitor all the locally available #Ollama instances. Of course, you can 𝘤𝘶𝘳𝘭 yourself, but why not have a tool in the history of btop/abtop ..
Only one 𝘴𝘩𝘦𝘭𝘭 script utilizing 𝘤𝘶𝘳𝘭, 𝘢𝘸𝘬 and 𝘫𝘲. The name is the architecture: one llama is a pet, several across machines is a farm.
Tons of hotkeys to change update frequency, re-discovery of servers, probing their VRAM, cycling color themes. GitHub Actions ensure high quality code.
So give it a try and/or write a better version, #GPLv3 allows it: https://github.com/marcelpetrick/ollamaFarm/
Ollama Farmer out 🧑🏻🌾🦙
New project: 𝐂𝐫𝐨𝐋𝐢𝐧𝐠𝐨 🇭🇷🇩🇪
Just wanted to share that I started the design and implementation of an app for learning Croatian.
The market for language-learning apps does not offer the combination I need, so it is time to roll our own custom software.
Also a playground for #Flutter and #Dart, since I have so far only used Kotlin for Android apps. And it will run on x86_64 Linux desktops as well. Maybe I’ll do an iOS version too.
Most of the preliminary work was spent on the design and concept. #Ideation is quite important in the age of agentic AI.
Of course, I will avoid writing code and keep you updated 😉
Final evaluation
The World Cup is over — actually for quite a while, but I never had the time to do the final evaluation. Outcome was fifth place (yes, from second to fifth), because those two missing entries really made me leave 7-9 points on the table (on average), which could have yielded a second or third place.
I will re-invest the gained 18€ into pizza for the team and use it for some discussions about morality (is agentic resolution allowed for such games?).
And I won: my initial goal of fetching back my investment of the starter fee was met. Good.
And I learnt how to orchestrate agents to solve non-SW-development tasks.
#agenticAI