Python
𝐂𝐨𝐝𝐞 𝐠𝐨𝐥𝐟 for a Python interpreter
When I was young, I enjoyed writing small, #cryptic code. Always happy to know some language quirk (in Turbo Pascal, Java, C, C++, #Python ..) which could save some characters. Small code is better code, like we all know 😉 Or not (common sense: smaller code is mostly unreadable and therefore harder to maintain.) And that game of writing minimal code is called Code golf.
A post by Austin Henley last week triggered me again. (Thank you.) He aimed to write a 𝐦𝐢𝐧𝐢𝐦𝐚𝐥 𝐏𝐲𝐭𝐡𝐨𝐧 𝐢𝐧𝐭𝐞𝐫𝐩𝐫𝐞𝐭𝐞𝐫 in initially 512 bytes, then figured out that at least 1024 are needed. So one kilobyte for an interpreter which can run a 𝐅𝐢𝐳𝐳-𝐁𝐮𝐳𝐳 program. An interpreter is a program whose job is: read the program code and execute it. And a Fizz-Buzz is a really simple coding test, similar to a Hello World. But Austin might be able to explain this better, since he is an ex-professor from Carnegie Mellon.
Anyway: so I tried to build my own version from scratch with an LLM as working partner and armed my C skills. Thirteen versions later I came down to 959 bytes, which can still handle real Python programs (of course, limited subset, just like the original 1024-byte version did). When I dropped some primitives I came down to 622 bytes, but then it was really only possible to execute the control version of that Fizz-Buzz test.
Shrinking gains came from:
* collapsing variable names to one letter
* deleting everything that is written for humans
* cleaning the input once
* swapping instructions for a shorter version (heavy testing and iteration on that)
* order of the sections — sometimes a better arrangement can save a repetition
As always: you can check the versions of the code yourself at https://github.com/marcelpetrick/codingWithGPT/tree/master/pythonInterpreterCodeGolf
And if now someone expected a clever outcome or clue or underlying message: there is none. 𝐏𝐮𝐫𝐞 𝐡𝐨𝐛𝐛𝐲.

Containerized 𝐆𝐞𝐫𝐦𝐚𝐧𝐃𝐮𝐛𝐈 📦
Some of you might remember I released GermanDubI this week – a tool with a neat UI/UX to replace the English audio track of YouTube videos with a German one. Works quite well and has already served its purpose several times. The kids could watch some interesting historical videos.
So, a release does not mean my work stops. Software engineering as a craft means you maintain the product after its release. #SDLC – maybe some have heard about it 😉
Using products also reveals some sporadic issues (dubbing could lead, in 5% of the runs, to a 100% CPU spin for ffmpeg, because of some overlapping tracks) – all known ones are fixed now. I bumped all dependencies.
And I did one thing I forgot: I containerized the whole app. So the Docker image is now available on #ghcr.
$ 𝐝𝐨𝐜𝐤𝐞𝐫 𝐩𝐮𝐥𝐥 𝐠𝐡𝐜𝐫.𝐢𝐨/𝐦𝐚𝐫𝐜𝐞𝐥𝐩𝐞𝐭𝐫𝐢𝐜𝐤/𝐠𝐞𝐫𝐦𝐚𝐧𝐝𝐮𝐛𝐢:𝐥𝐚𝐭𝐞𝐬𝐭
And after that, it is a one- or two-liner copy-pasted to get it running. For 𝐱𝟔𝟒 and 𝐀𝐑𝐌 platforms.
I’ve already seen 16 downloads (🥹), so definitely not “no one” is using it. On the other hand: 𝐈 𝐚𝐥𝐰𝐚𝐲𝐬 𝐰𝐨𝐧𝐝𝐞𝐫 𝐢𝐟 𝐢𝐭 𝐦𝐚𝐤𝐞𝐬 𝐬𝐞𝐧𝐬𝐞 𝐭𝐨 𝐠𝐨 𝐭𝐡𝐞 𝐥𝐚𝐬𝐭 𝐦𝐢𝐥𝐞 𝐚𝐧𝐝 𝐜𝐨𝐧𝐭𝐚𝐢𝐧𝐞𝐫𝐢𝐳𝐞 𝐚𝐩𝐩𝐬. What is your view?
ps. the release version 0.4.2 is just a random match, not forced

My new image compression algorithm achieves rates of up to 632:1
𝐭𝐥;𝐝𝐫 𝐥𝐥𝐦𝐏𝐄𝐆 𝐜𝐨𝐦𝐩𝐫𝐞𝐬𝐬𝐞𝐬 𝐢𝐦𝐚𝐠𝐞𝐬 𝐢𝐧𝐭𝐨 𝐥𝐚𝐧𝐠𝐮𝐚𝐠𝐞, 𝐧𝐨𝐭 𝐩𝐢𝐱𝐞𝐥𝐬. 𝐀 𝐯𝐢𝐬𝐢𝐨𝐧 𝐦𝐨𝐝𝐞𝐥 𝐭𝐮𝐫𝐧𝐬 𝐭𝐡𝐞 𝐢𝐦𝐚𝐠𝐞 𝐢𝐧𝐭𝐨 𝐚 𝐜𝐨𝐦𝐩𝐚𝐜𝐭 𝐉𝐒𝐎𝐍 𝐝𝐞𝐬𝐜𝐫𝐢𝐩𝐭𝐢𝐨𝐧.
This week, a meme made the rounds about a young prodigy inventing a new way to compress photos. The idea behind it: derive the content of the image with a multimodal #vision-language model, then store this instead of the image. And when you want to view it, an #image-generation model recreates the content.
Simple. 𝐀𝐧𝐝 𝐭𝐨𝐭𝐚𝐥𝐥𝐲 𝐋𝐎𝐒𝐒𝐘.
Running #JPEG with a quality setting 10 looks like archival preservation in comparison.
I saw the meme several times in my stream. Instead of laughing and getting back to work, I did the obvious thing: I built it.
Meet #llmPEG.
You get a tool for compression (driven by #Qwen-VL inside #ollama) and decompression (either #ComfyUI or the image-gen skill from #codex).
After the initial prototype was working, I did some refinement of the prompts with a GAN-ish style of loop: until we had – with the given metric – a sufficiently fitting reproduction.
Please don’t ask about wall-clock performance.
Compression: ~20 seconds.
Decompression: ~30 seconds.
But the compression rate! Always at least 100:1, if not better: check this page with examples: https://marcelpetrick.github.io/llmPEG/expanded.html
𝐀𝐭 𝐟𝐢𝐫𝐬𝐭 𝐢𝐭 𝐰𝐚𝐬 𝐚 𝐦𝐞𝐦𝐞, 𝐧𝐨𝐰 𝐢𝐭 𝐢𝐬 𝐚 𝐭𝐨𝐨𝐥 😉
Source code, if you want to run it yourself and/or contribute: https://github.com/marcelpetrick/llmPEG/
Video:
𝐇𝐨𝐰 𝐡𝐨𝐦𝐨𝐠𝐞𝐧𝐞𝐨𝐮𝐬 𝐚𝐫𝐞 𝐦𝐲 𝐜𝐥𝐚𝐮𝐝𝐞.𝐦𝐝/𝐚𝐠𝐞𝐧𝐭𝐬.𝐦𝐝?
Out of curiosity I spent some time gathering and evaluating data, because during a discussion I was highly suspicious that a single agent instruction markdown (I prefer 𝘢𝘨𝘦𝘯𝘵𝘴.𝘮𝘥, just so you know) can cover all the custom aspects of a project. After all: if a generic agents.md can cover the needs of several projects, then we are in the domain of line work. And not of pushing the frontier.
Anyway: looks like I was handling 30 projects with #agenticAI in the past half year (arbitrary cut-off). The almighty collection git-repo “𝐜𝐨𝐝𝐢𝐧𝐠𝐖𝐢𝐭𝐡𝐆𝐏𝐓” is still alive and kicking, therefore we had the case of one repo with SEVERAL agent.mds. Even with different naming (see where this goes?)
𝐒𝐨 𝐡𝐞𝐫𝐞 𝐚𝐫𝐞 𝐭𝐡𝐞 𝐫𝐞𝐬𝐮𝐥𝐭𝐬:
* 19 times I let them be named agents.md, only 11 times claude.md
* the language style was only 24% binding (must/never/always) – 42% advisory (should/prefer) and the rest unmarked
* the sections contained 73% rules; 13% project description guides, 6% command sheets and 7% reference material
* the heaviest context budget was/is paid for the one in “𝘤𝘭𝘰𝘵𝘩𝘦𝘴𝘚𝘦𝘢𝘳𝘤𝘩” – almost 7k tokens with 45 rules – yes, I spent a lot of time automating my shopping. This agents.md is more than double the size of any other in my analyzed projects!
* “𝐯𝐞𝐫𝐢𝐟𝐲 𝐛𝐞𝐟𝐨𝐫𝐞 𝐜𝐥𝐚𝐢𝐦𝐢𝐧𝐠 𝐬𝐮𝐜𝐜𝐞𝐬𝐬” is the most prominent instruction – appeared in 60% of my agent guides
* “one concern per commit” appeared only in 20% – which is weird. Everybody who works with me knows that 𝐈 𝐋𝐎𝐕𝐄 𝐚𝐭𝐨𝐦𝐢𝐜 𝐜𝐨𝐦𝐦𝐢𝐭𝐬 ☢️
* only two agents.md files had not changed over the past 90 days – a sign that this guidance is a living object; 𝐞𝐦𝐛𝐫𝐚𝐜𝐞 𝐜𝐡𝐚𝐧𝐠𝐞!
* 𝐨𝐧𝐥𝐲 𝐭𝐡𝐫𝐞𝐞 𝐫𝐞𝐩𝐨𝐬𝐢𝐭𝐨𝐫𝐢𝐞𝐬 𝐜𝐚𝐫𝐫𝐢𝐞𝐝 𝐛𝐲𝐭𝐞-𝐢𝐝𝐞𝐧𝐭𝐢𝐜𝐚𝐥 𝐚𝐠𝐞𝐧𝐭𝐬.𝐦𝐝: why? It was my early phase, when I did really work with files while doing agentic software engineering, silly me 👶🏻
Ok, if you want to see more, check the images.
Else: 𝐡𝐨𝐰 𝐝𝐨 𝐲𝐨𝐮 𝐡𝐚𝐧𝐝𝐥𝐞 𝐲𝐨𝐮𝐫 𝐚𝐠𝐞𝐧𝐭 𝐡𝐚𝐫𝐧𝐞𝐬𝐬𝐞𝐬? 𝐆𝐮𝐢𝐝𝐞 𝐨𝐫 𝐥𝐞𝐭 𝐭𝐡𝐞𝐦 𝐫𝐨𝐚𝐦 𝐰𝐢𝐥𝐝?
If someone else has done a review, post your results as well in the comments. I am interested. If someone needs the code for running this automatically – ping me, I’ll guide you to the repo.
#harness #claude #codex #anthropic #openai #ai


Videos automatisch übersetzen: 𝐆𝐞𝐫𝐦𝐚𝐧𝐃𝐮𝐛𝐈
Eine clevere technische Lösung zu bauen ist meistens gar nicht das eigentliche Problem. Viel interessanter ist doch: Wie baut man etwas, das Leute wirklich benutzen wollen?
Ich wollte den Kindern ein richtig gutes Video über die römische Armee zeigen. Nicht irgendein trockenes Erklärvideo, sondern eins, wo man denkt: Okay, das ist cool, da lernt man was. Problem war nur: die guten Videos waren auf Englisch.
Klar kann man sagen: Ist doch super, dann lernen die Kinder gleich noch Englisch. Stimmt. Aber wenn man zu viele Sachen gleichzeitig machen möchte, wird halt alles ein bisschen schlechter. Manchmal sollen sie einfach ein cooles Video schauen und dabei was lernen.
Also dachte ich: 𝘈𝘤𝘩, 𝘥𝘢𝘴 𝘬𝘢𝘯𝘯 𝘥𝘰𝘤𝘩 𝘯𝘪𝘤𝘩𝘵 𝘴𝘰 𝘴𝘤𝘩𝘸𝘦𝘳 𝘴𝘦𝘪𝘯. Video transkribieren, übersetzen, neue Tonspur drüber und fertig.
Lass uns das mal schnell bauen.
Aus zwei Stunden wurden dann halt 𝐳𝐰𝐞𝐢 𝐓𝐚𝐠𝐞.
Die erste Version war ein Command Line Tool. Hat funktioniert. Aber wenn ich das so veröffentliche, benutzt das halt kaum jemand. Man sieht keinen Fortschritt, Fehler sind unübersichtlich, mehrere Videos parallel zu verarbeiten ist mühsam und wenn irgendwo etwas schiefläuft, will man nicht jedes Mal den kompletten Workflow neu starten.
Also habe ich gedacht: 𝐃𝐚𝐧𝐧 𝐡𝐚𝐥𝐭 𝐫𝐢𝐜𝐡𝐭𝐢𝐠.
Schönes UI und Benutzerführung, mehrere Sprachen, parallele Verarbeitung, Fortschritt, Statistiken, Fehler direkt sichtbar, einzelne Schritte neu starten, Transkriptionen bearbeiten und gezielt neu generieren.
Und genau da merkt man halt den Unterschied zwischen einer technischen Lösung und einem Produkt.
Zeigst du jemandem ein Terminal und sagst: Damit kann ich Videos automatisch übersetzen, kommt meistens ein „Ah, cool“.
Zeigst du dieselbe Funktionalität in einer Oberfläche, wo sofort klar ist, was passiert und wo man einfach eingreifen kann, kommt plötzlich: „Kann ich das ausprobieren?“
Genau das wird meiner Meinung nach bei Software oft unterschätzt. Es reicht nicht, dass etwas clever ist und funktioniert. Es muss auch komfortabel sein. Leicht verständlich. Leicht benutzbar. Und wenn etwas schiefläuft, muss man trotzdem weiterkommen.
Das gilt übrigens auch fürs Setup. Wer 𝐆𝐞𝐫𝐦𝐚𝐧𝐃𝐮𝐛𝐈 ausprobieren möchte, klont einfach das GitHub Repo (https://github.com/marcelpetrick/GermanDubI), kopiert drei Befehle aus der Anleitung ins Terminal und das Ding läuft.
Die technischen Details spare ich mir hier. Python, TypeScript, Uvicorn, Parallelverarbeitung, 95% Testcoverage, Pipelines und der ganze Kram. Darüber könnte ich noch stundenlang reden, weil mir das halt Spaß macht, aber am Ende interessiert das sowieso kaum jemanden.
Für mich ist der interessantere Teil: 𝐀𝐮𝐬 𝐞𝐢𝐧𝐞𝐫 𝐤𝐥𝐞𝐢𝐧𝐞𝐧 𝐈𝐝𝐞𝐞 𝐞𝐢𝐧𝐞 𝐋ö𝐬𝐮𝐧𝐠 𝐳𝐮 𝐛𝐚𝐮𝐞𝐧, 𝐝𝐢𝐞 𝐧𝐢𝐜𝐡𝐭 𝐧𝐮𝐫 𝐭𝐞𝐜𝐡𝐧𝐢𝐬𝐜𝐡 𝐟𝐮𝐧𝐤𝐭𝐢𝐨𝐧𝐢𝐞𝐫𝐭, 𝐬𝐨𝐧𝐝𝐞𝐫𝐧 𝐬𝐢𝐜𝐡 𝐚𝐮𝐜𝐡 𝐰𝐢𝐞 𝐞𝐢𝐧 𝐏𝐫𝐨𝐝𝐮𝐤𝐭 𝐚𝐧𝐟ü𝐡𝐥𝐭.


ESE 2026-Kongress-Selektor – 𝐔𝐬𝐞-𝐜𝐚𝐬𝐞 𝐟ü𝐫 𝐂𝐮𝐬𝐭𝐨𝐦 𝐔𝐗-𝐃𝐞𝐬𝐢𝐠𝐧
Zu Beginn die Klärung, dass ich weder mit dem Embedded Software Kongress verbandelt bin, noch bezahlt wurde etc.
Ich würde gern dieses Jahr nach Sindelfingen reisen, also war es Zeit, die Agenda zu studieren. Die Webseiten bieten einen guten Überblick.
ABER: Sie könnten etwas komfortabler in der Bedienung sein. Denn für eine fundierte Entscheidung brauche ich die Info, was der Vortrag neben der spannenden Headline wirklich aufzeigen möchte. Jeden Vortrag im neuen Tab öffnen und laden lassen? Nee, bitte nicht. Ebenfalls: eine Vorselektion für die für mich relevanten Bereiche: 𝐏𝐫𝐨𝐣𝐞𝐤𝐭- 𝐮𝐧𝐝 𝐓𝐞𝐚𝐦-𝐌𝐚𝐧𝐚𝐠𝐞𝐦𝐞𝐧𝐭, 𝐀𝐠𝐞𝐧𝐭𝐢𝐜 𝐀𝐈, 𝐒𝐤𝐚𝐥𝐢𝐞𝐫𝐮𝐧𝐠.
Also schnell den 𝐄𝐒𝐄_𝐊𝐨𝐧𝐠𝐫𝐞𝐬𝐬_𝐒𝐞𝐥𝐞𝐤𝐭𝐨𝐫 (https://github.com/marcelpetrick/ESE_Kongress_Selektor) in #Python implementiert.
Was brauchen wir hierfür? Einen #Scraper und eine statische Webseite. Der Export der Selektionen erfolgt via JSON. Die Struktur der Seiten wird mehr oder weniger übernommen.
Rasend schnell, Details zum Vortrag werden via Tooltip (statt auf einer neuen Seite) angezeigt, Filterung ist möglich.
Repo klonen und die 𝘱𝘺𝘵𝘩𝘰𝘯3 𝘳𝘶𝘯.𝘱𝘺 ausführen, kurz warten und los geht’s.
𝐖𝐞𝐫 𝐩𝐥𝐚𝐧𝐭 𝐳𝐮𝐦 𝐄𝐒𝐄 𝐳𝐮 𝐟𝐚𝐡𝐫𝐞𝐧? 𝐀𝐧 𝐰𝐞𝐥𝐜𝐡𝐞𝐧 𝐓𝐚𝐠𝐞𝐧?
An die Organisatoren des @ESE: Falls ihr etwas vom Design übernehmen wollt – gern, die GPLv3 macht es möglich.
Video (nicht sichtbar in Vorschau)
Good news: 𝐋𝐕𝐆𝐋 YAML translations with 𝐂𝐮𝐭𝐞𝐋𝐢𝐧𝐠𝐨𝐄𝐱𝐩𝐫𝐞𝐬𝐬 𝟎.𝟑.𝟎
Since #Qt is not the only champion in the embedded domain, I’ve expanded the supported frameworks by making it possible to run it on the #i18n files from #LVGL as well. Maybe it is handy for someone else too 😉
The new mode is invoked with --lvgl-yaml, and you have to do it explicitly. The existing usage for TS files remains unchanged.
The source YAML files also stay untouched, so the result is written to a file named for each output language.
In the background, I also did some other plumbing, which had been on the list for a while: GitHub Actions now also cover the dependency graph, neat badges showing the pipeline states in the README.md, updated dependencies, and some quality hardening. So we have 58 automated tests now, 100% statement coverage, and Pylint reports 10/10.
That polishing and the above-mentioned feature are the result of continuous market review and constant adaptation. New competitors and technical standards emerge; as developers, we should be ready to embrace change and adapt.
Give me feedback if some other translation files need coverage as well.
Link to to the repo: https://github.com/marcelpetrick/CuteLingoExpress


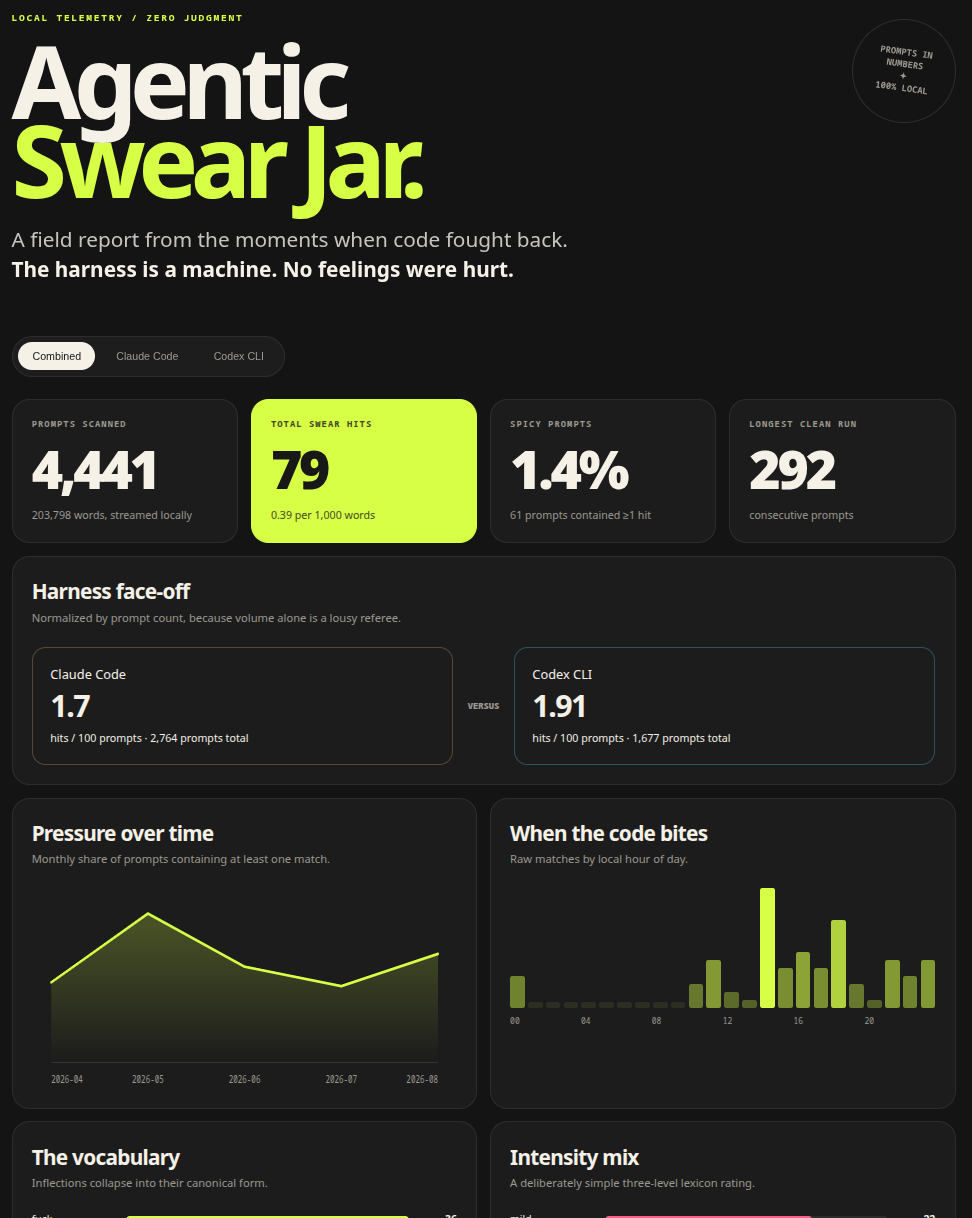
𝐎𝐧𝐥𝐲 𝟐% of my 𝐩𝐫𝐨𝐦𝐩𝐭𝐬 contain 𝐩𝐫𝐨𝐟𝐚𝐧𝐢𝐭𝐲
Testing Muse Glimmer lead to some frustration, so I started the next prompt with something I wouldn’t write professionally.
And this led to the question: how often do I do this? I would have guessed that 10% of my machine-human interactions contain some swear words.
But why guess when you can evaluate the data and produce hard facts?
Therefore I prepared 🫙 𝐀𝐠𝐞𝐧𝐭𝐢𝐜 𝐒𝐰𝐞𝐚𝐫 𝐉𝐚𝐫 as project on GitHub, which evaluates both your 𝐂𝐨𝐝𝐞𝐱 and 𝐂𝐥𝐚𝐮𝐝𝐞 𝐂𝐨𝐝𝐞 logs and gives you on the CLI a short two liner. And additionally you receive an HTML page in nice green IBM 3279-style. All locally, no AI or models involved, just some Python and HTML.
It will reveal to you how many swearwords were used, their frequency, streaks without swearing, which hour of the day the tension rises high, etc ..
What do you think? Anyone has a higher score to offer? Leave me a comment.
GitHub: https://github.com/marcelpetrick/AgenticSwearJar
PDF with full feature view:
Screenshot:
𝐂𝐥𝐨𝐮𝐝 𝐀𝐏𝐈𝐬 𝐚𝐫𝐞 𝐞𝐱𝐩𝐞𝐧𝐬𝐢𝐯𝐞. 𝐖𝐚𝐭𝐞𝐫𝐦𝐞𝐥𝐨𝐧 𝐢𝐬 𝐧𝐨𝐭. 🍉
Vision models grow in their capabilities while the execution demands way fewer resources.
Means: my sales slip scanner-project from two years ago needed an upgrade. Before I was using GPT-4 Vision via the @OpenAI API, which costs you control over your data and a few cents for every analysis.
Now, after intensive benchmarking across a range of 15 models (with 𝐎𝐥𝐥𝐚𝐦𝐚) and some surprising regressions (newer harness doesn’t mean the models execute faster; it can also mean they suddenly run into model load errors…), I put my money on 𝐐𝐰𝐞𝐧𝟑.𝟓:𝟒𝐁. A casual language model with a 𝐯𝐢𝐬𝐢𝐨𝐧 𝐞𝐧𝐜𝐨𝐝𝐞𝐫. My own benchmark over the selected models against the huge sample size of three receipts: all three were successfully evaluated. 😉
Then I built a 𝐡𝐨𝐭-𝐟𝐨𝐥𝐝𝐞𝐫-𝐜𝐨𝐧𝐜𝐞𝐩𝐭 around the script, and it works (thank you @Mr Zahorsky — without whom I would have never come across that idea). For instance: in less than ten seconds, 13 samples were processed, and you get the result sum plus a fancy HTML overview for comparison.
𝐃𝐚𝐭𝐚 𝐞𝐧𝐭𝐫𝐲 can be done for cheap: give the kids the smartphone, snap all receipts, throw out some watermelon slices 🍉😉
If you want to run the tool as well, check my GitHub: https://github.com/marcelpetrick/sales-slip-scanner-ng. As said: a local GPU is the only thing you need; 𝐧𝐨 𝐜𝐥𝐨𝐮𝐝, 𝐧𝐨 𝐀𝐏𝐈 𝐤𝐞𝐲𝐬, 𝐧𝐨 𝐜𝐫𝐞𝐝𝐢𝐭 𝐜𝐚𝐫𝐝. Everything is now self-hosted. You’ll also find the benchmark of the vision models there, including the results.
𝐓𝐡𝐞 𝐛𝐢𝐠 𝐪𝐮𝐞𝐬𝐭𝐢𝐨𝐧 𝐢𝐬: 𝐰𝐡𝐚𝐭 𝐬𝐡𝐨𝐮𝐥𝐝 𝐈 𝐚𝐮𝐭𝐨𝐦𝐚𝐭𝐞 𝐧𝐞𝐱𝐭 𝐰𝐢𝐭𝐡 𝐚 𝐥𝐨𝐜𝐚𝐥 𝐯𝐢𝐬𝐢𝐨𝐧 𝐦𝐨𝐝𝐞𝐥? 𝐖𝐡𝐚𝐭 𝐰𝐨𝐮𝐥𝐝 𝐲𝐨𝐮 𝐝𝐨?
#neverstoplearning


𝐌𝐲 𝐚𝐩𝐩𝐬 𝐚𝐫𝐞 𝐧𝐨𝐭 𝐚𝐛𝐚𝐧𝐝𝐨𝐧𝐰𝐚𝐫𝐞!
Yesterday, #RitterRadar got some updates: first, all dependencies were refreshed (no more CVEs); then I fixed some bugs I had noticed over the past few weeks; and finally, the best news: a new feature that gives you a copyable list of the events matching your current filter.
So, for instance, if you live near Potsdam and want to see all medieval events within 50 km over the next two months – you get this:
——-
04. Juli 2026 | Kinder- und Sommerfest in Gannahall 2026 | 14641 Nauen (26 km)
04. Juli 2026 – 05. Juli 2026 | Mythologie und Handwerk des Mittelalters 2026 | 15569 Woltersdorf (47 km)
22. Aug. 2026 – 23. Aug. 2026 | Sommerfest Lübarser Hofkulturdiverse Konzerte | 13469 Berlin (30 km)
29. Aug. 2026 | Mittelalterliches zum Ackerbürgerfest | 14641 Nauen (26 km)
——-
#FastAPI #WebScraping #OpenStreetMap #Geocoding #OpenSource #EventDiscovery
URL to the GitHub-project: https://github.com/marcelpetrick/RitterRadar if you haven’t given it a try yet ⚔️🐉
