𝐓𝐡𝐞 𝐟𝐢𝐫𝐬𝐭 𝐠𝐚𝐦𝐞 𝐦𝐲 𝐤𝐢𝐝𝐬 𝐚𝐩𝐩𝐫𝐨𝐯𝐞𝐝
I like good turn-based offline games. Recently, the kids brought home one that I won’t name here because my GitHub Pages–backed browser game is a shameless copy.
If you want to play it (free and safe): https://marcelpetrick.github.io/recognizer/
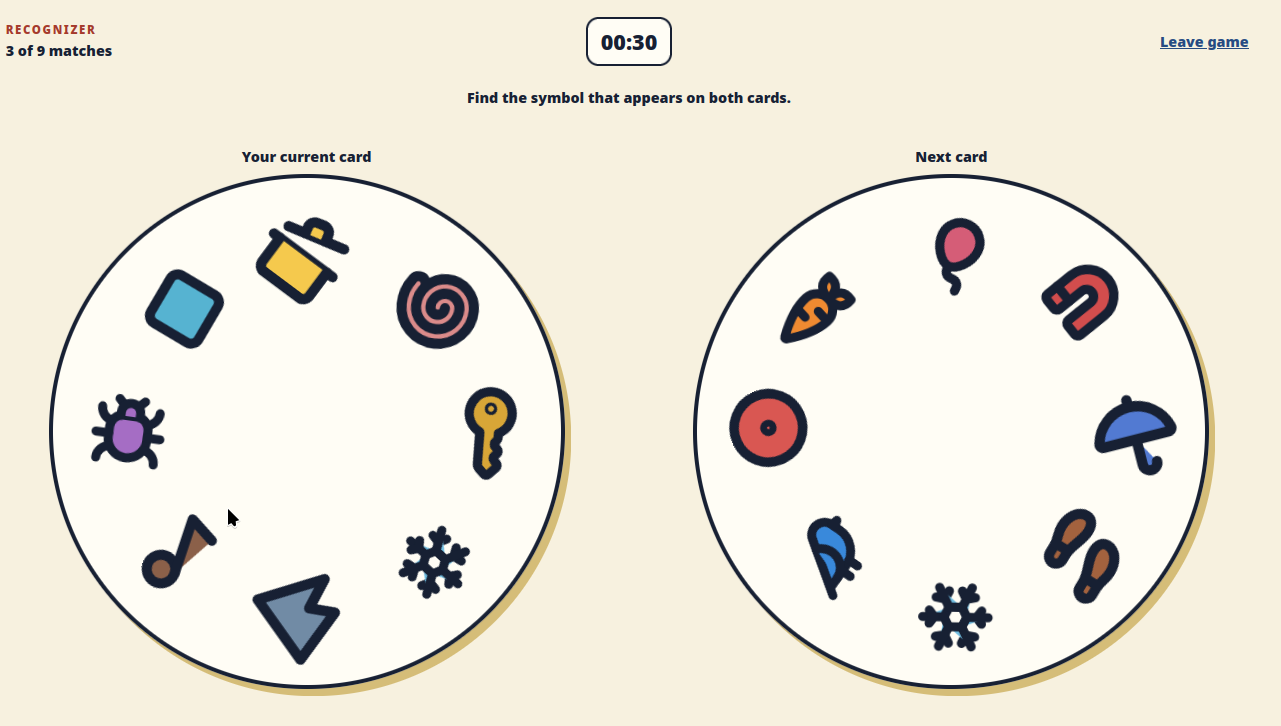
𝗧𝗵𝗲 𝗿𝘂𝗹𝗲𝘀 𝘁𝗮𝗸𝗲 𝘁𝗲𝗻 𝘀𝗲𝗰𝗼𝗻𝗱𝘀 𝘁𝗼 𝗲𝘅𝗽𝗹𝗮𝗶𝗻: 𝘛𝘸𝘰 𝘤𝘢𝘳𝘥𝘴. 𝘌𝘪𝘨𝘩𝘵 𝘴𝘺𝘮𝘣𝘰𝘭𝘴 𝘦𝘢𝘤𝘩. 𝘌𝘹𝘢𝘤𝘵𝘭𝘺 𝘰𝘯𝘦 𝘮𝘢𝘵𝘤𝘩. 𝗙𝗶𝗻𝗱 𝘁𝗵𝗲 𝗺𝗮𝘁𝗰𝗵 𝗳𝗮𝘀𝘁𝗲𝗿 𝘁𝗵𝗮𝗻 𝘆𝗼𝘂𝗿 𝗺𝗮𝘁𝗲𝘀.
It is super simple, but pattern matching requires concentration, and you have to be quick. 𝗜𝘁’𝘀 𝗴𝗿𝗲𝗮𝘁 𝗳𝘂𝗻 𝗲𝘃𝗲𝗻 𝗮𝘀 𝗮 𝘀𝗶𝗻𝗴𝗹𝗲 𝗽𝗹𝗮𝘆𝗲𝗿 with a local high-score list.
Building it raised three useful questions:
* 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝗴𝘂𝗮𝗿𝗮𝗻𝘁𝗲𝗲 that rule across all 𝟏,𝟓𝟗𝟔 possible card pairs?
* 𝗛𝗼𝘄 𝗱𝗼 𝘆𝗼𝘂 𝘁𝘂𝗿𝗻 a shared game into a good single-player challenge?
* 𝗛𝗼𝘄 𝗺𝘂𝗰𝗵 𝗶𝗻𝗳𝗿𝗮𝘀𝘁𝗿𝘂𝗰𝘁𝘂𝗿𝗲 does a small browser game actually need?
The mathematical part uses a finite projective plane. 𝗧𝗵𝗲 𝘁𝗲𝘀𝘁 𝘀𝘂𝗶𝘁𝗲 𝘃𝗲𝗿𝗶𝗳𝗶𝗲𝘀 𝗲𝘃𝗲𝗿𝘆 𝗽𝗼𝘀𝘀𝗶𝗯𝗹𝗲 𝗰𝗮𝗿𝗱 𝗽𝗮𝗶𝗿.
The product stays deliberately small: 10, 20, or 50 cards, a timer, and local high scores. 𝘕𝘰 𝘢𝘤𝘤𝘰𝘶𝘯𝘵𝘴. 𝘕𝘰 𝘨𝘭𝘰𝘣𝘢𝘭 𝘳𝘢𝘯𝘬𝘪𝘯𝘨𝘴. 𝘕𝘰 𝘣𝘢𝘤𝘬𝘦𝘯𝘥.
𝗔 𝘀𝗶𝗱𝗲 𝗻𝗼𝘁𝗲 𝗳𝗼𝗿 𝘁𝗵𝗼𝘀𝗲 𝗶𝗻𝘁𝗲𝗿𝗲𝘀𝘁𝗲𝗱 𝗶𝗻 𝘀𝗼𝗳𝘁𝘄𝗮𝗿𝗲 𝗱𝗲𝗹𝗶𝘃𝗲𝗿𝘆
I also used the project as a compact, end-to-end SDLC example: written requirements, scope, and acceptance criteria; separated and testable domain logic; versioned storage with migration handling; unit, component, browser, mobile, and accessibility tests; formatting, linting, type checking, and build gates; locked dependencies with automated updates; and repeatable PWA deployment through GitHub Actions and GitHub Pages.
𝐈𝐟 𝐲𝐨𝐮 𝐭𝐡𝐢𝐧𝐤 𝐲𝐨𝐮 𝐚𝐫𝐞 𝐪𝐮𝐢𝐜𝐤𝐞𝐫: 𝐩𝐥𝐚𝐲 𝐚𝐧𝐝 𝐩𝐨𝐬𝐭 𝐲𝐨𝐮𝐫 𝐬𝐜𝐨𝐫𝐞 🤗
𝐂𝐥𝐨𝐮𝐝 𝐀𝐏𝐈𝐬 𝐚𝐫𝐞 𝐞𝐱𝐩𝐞𝐧𝐬𝐢𝐯𝐞. 𝐖𝐚𝐭𝐞𝐫𝐦𝐞𝐥𝐨𝐧 𝐢𝐬 𝐧𝐨𝐭. 🍉
Vision models grow in their capabilities while the execution demands way fewer resources.
Means: my sales slip scanner-project from two years ago needed an upgrade. Before I was using GPT-4 Vision via the @OpenAI API, which costs you control over your data and a few cents for every analysis.
Now, after intensive benchmarking across a range of 15 models (with 𝐎𝐥𝐥𝐚𝐦𝐚) and some surprising regressions (newer harness doesn’t mean the models execute faster; it can also mean they suddenly run into model load errors…), I put my money on 𝐐𝐰𝐞𝐧𝟑.𝟓:𝟒𝐁. A casual language model with a 𝐯𝐢𝐬𝐢𝐨𝐧 𝐞𝐧𝐜𝐨𝐝𝐞𝐫. My own benchmark over the selected models against the huge sample size of three receipts: all three were successfully evaluated. 😉
Then I built a 𝐡𝐨𝐭-𝐟𝐨𝐥𝐝𝐞𝐫-𝐜𝐨𝐧𝐜𝐞𝐩𝐭 around the script, and it works (thank you @Mr Zahorsky — without whom I would have never come across that idea). For instance: in less than ten seconds, 13 samples were processed, and you get the result sum plus a fancy HTML overview for comparison.
𝐃𝐚𝐭𝐚 𝐞𝐧𝐭𝐫𝐲 can be done for cheap: give the kids the smartphone, snap all receipts, throw out some watermelon slices 🍉😉
If you want to run the tool as well, check my GitHub: https://github.com/marcelpetrick/sales-slip-scanner-ng. As said: a local GPU is the only thing you need; 𝐧𝐨 𝐜𝐥𝐨𝐮𝐝, 𝐧𝐨 𝐀𝐏𝐈 𝐤𝐞𝐲𝐬, 𝐧𝐨 𝐜𝐫𝐞𝐝𝐢𝐭 𝐜𝐚𝐫𝐝. Everything is now self-hosted. You’ll also find the benchmark of the vision models there, including the results.
𝐓𝐡𝐞 𝐛𝐢𝐠 𝐪𝐮𝐞𝐬𝐭𝐢𝐨𝐧 𝐢𝐬: 𝐰𝐡𝐚𝐭 𝐬𝐡𝐨𝐮𝐥𝐝 𝐈 𝐚𝐮𝐭𝐨𝐦𝐚𝐭𝐞 𝐧𝐞𝐱𝐭 𝐰𝐢𝐭𝐡 𝐚 𝐥𝐨𝐜𝐚𝐥 𝐯𝐢𝐬𝐢𝐨𝐧 𝐦𝐨𝐝𝐞𝐥? 𝐖𝐡𝐚𝐭 𝐰𝐨𝐮𝐥𝐝 𝐲𝐨𝐮 𝐝𝐨?
#neverstoplearning


𝗜 𝗥𝗮𝗻 𝗮 𝟮𝟳𝗕 𝗠𝗼𝗱𝗲𝗹 𝗼𝗻 𝗮𝗻 𝟴𝗚𝗕 𝗚𝗣𝗨.
𝟰𝟬 𝗺𝗶𝗻𝘂𝘁𝗲𝘀. That’s all it took me to get Bonsai 27B running locally on an RTX A2000 Laptop GPU with just 8GB of VRAM.
Bonsai 27B is based on Qwen 3.6, but uses PrismML’s custom native 𝟏-𝐛𝐢𝐭 𝐁𝐨𝐧𝐬𝐚𝐢 format, reducing the model to just 3.9GB. A specialized 𝐥𝐥𝐚𝐦𝐚.𝐜𝐩𝐩 fork implements custom CUDA kernels for the 1-bit inference path, making it possible to run the model directly on an 8GB GPU. The runtime exposes an OpenAI-compatible API, so existing tools and agents work without modification.
Performance is a different topic: 15 down to 9 tokens/s.
If you want to give it a try: find my notes and setup-scripts at GitHub: https://github.com/marcelpetrick/codingWithGPT/tree/master/bonsaiTestrun

𝐌𝐲 𝐚𝐩𝐩𝐬 𝐚𝐫𝐞 𝐧𝐨𝐭 𝐚𝐛𝐚𝐧𝐝𝐨𝐧𝐰𝐚𝐫𝐞!
Yesterday, #RitterRadar got some updates: first, all dependencies were refreshed (no more CVEs); then I fixed some bugs I had noticed over the past few weeks; and finally, the best news: a new feature that gives you a copyable list of the events matching your current filter.
So, for instance, if you live near Potsdam and want to see all medieval events within 50 km over the next two months – you get this:
——-
04. Juli 2026 | Kinder- und Sommerfest in Gannahall 2026 | 14641 Nauen (26 km)
04. Juli 2026 – 05. Juli 2026 | Mythologie und Handwerk des Mittelalters 2026 | 15569 Woltersdorf (47 km)
22. Aug. 2026 – 23. Aug. 2026 | Sommerfest Lübarser Hofkulturdiverse Konzerte | 13469 Berlin (30 km)
29. Aug. 2026 | Mittelalterliches zum Ackerbürgerfest | 14641 Nauen (26 km)
——-
#FastAPI #WebScraping #OpenStreetMap #Geocoding #OpenSource #EventDiscovery
URL to the GitHub-project: https://github.com/marcelpetrick/RitterRadar if you haven’t given it a try yet ⚔️🐉

𝐐𝐭 𝐂𝐫𝐞𝐚𝐭𝐨𝐫 𝐬𝐩𝐞𝐥𝐥𝐜𝐡𝐞𝐜𝐤 — 𝐧𝐨𝐰 𝐰𝐢𝐭𝐡 𝐐𝐌𝐋 𝐬𝐮𝐩𝐩𝐨𝐫𝐭
I never wrote a #QtCreator #plugin before. Somehow I always avoided that, because first you have to set up your environment, then build a husk, make it build, yada yada.
But the spellchecker plugin from Carel Combrink was missing support for QML-type files for years now. C++ parsing existed, #QML did not.
𝗦𝗼 𝗜 𝗲𝘅𝗽𝗮𝗻𝗱𝗲𝗱 𝗶𝘁.
New QML parser added next to the existing C++ parser. As you know: QML is different from C++ 😉
It now scans QML comments and user-visible string literals:
* // line comments
* /* block comments */
* double-quoted strings
* single-quoted strings
* template literals
It also tries hard to not be annoying. It ignores QML/JavaScript code tokens like imports, ids, property names, bindings, and component names. URLs, emails, pure numbers, color values, and all-caps words are filtered out as well.
Source positions are preserved, so underlines and replacements land where they should. It works for current-file and project-wide checks, with background processing, reparsing, and settings for comments and string literals.
Lots of #testing. Unit tests, yes. But also manual testing, because certain aspects were not part of my initial implementation plan. As always.
So now you can use any Hunspell dictionary to check your QML files for typos and get them fixed.
Typos in code and comments are a real concentration breaker while reading code.
𝗠𝗶𝘀𝘀𝗶𝗼𝗻 𝗱𝗼𝗻𝗲. 𝗔𝗻𝗼𝘁𝗵𝗲𝗿 𝘁𝗵𝗶𝗻𝗴 𝗹𝗲𝗮𝗿𝗻𝗲𝗱. 𝗔𝗻𝗱 𝗺𝗮𝘆𝗯𝗲 𝘁𝗵𝗲 𝗽𝗮𝘁𝗰𝗵 𝗶𝘀 𝗮𝗰𝗰𝗲𝗽𝘁𝗲𝗱.
If someone really wants to check the patch themselves on GitHub:
https://github.com/CJCombrink/SpellChecker-Plugin/pull/197
Thanks to Carel Combrink and the other contributors for the existing work this builds on.
𝐒𝐭𝐚𝐧𝐝𝐢𝐧𝐠 𝐨𝐧 𝐭𝐡𝐞 𝐬𝐡𝐨𝐮𝐥𝐝𝐞𝐫𝐬 𝐨𝐟 𝐠𝐢𝐚𝐧𝐭𝐬.
#Spellchecking


